We study the problem of Sparse Regression, a landmark problem in the domain of Machine Learning, Statistics and Optimization which finds numerous applications in Compressed Sensing, model compression, high dimensional statistics, bio-informatics, resource constrained machine learning and more. Sparse Regression can be written down as an optimization problem as
¯𝐱=argmin‖𝐱‖0≤𝑠∗𝑓(𝐱)where 𝐱 ∈ℝ𝑑, 𝑠∗ much smaller than 𝑑, the ambient dimension, ‖⋅‖0 is the ℓ0 norm that denotes the number of non-zero elements of its arguments, and 𝑓 is a real valued function.
Our focus has been on the linear version of the problem where given 𝑛 samples of 𝑑 dimensional data 𝐀 ∈ℝ𝑛×𝑑 and a response vector 𝐲 ∈ℝ𝑑, we want to recover a 𝑠∗-sparse vector ¯𝐱 that minimizes the squared loss function ‖𝐀𝐱−𝐲‖22. However, this problem can be shown to be NP-hard via a reduction to 3-set cover, nonetheless this problem has been studied under a variety of assumptions such as the ones below
- Mutual Incoherence - Implies that the |⟨𝐀𝑖,𝐀𝑗⟩| should be bounded by some small positive real number 𝑀 for all 𝑖 ≠𝑗. In specific it can be shown OMP (which we will discuss in detail below) can recover ¯𝐱 in exactly 𝑠∗ steps if 𝑀 ≤12𝑠∗−1. Refer Theorem 5.14, Foucart and Rauhut for a short proof. Note that this can be equivalently written as ∥𝑣𝑒𝑐(𝐀𝑇𝐀−𝐈𝑑)∥∞≤𝑀.
- Restricted Isometry Property (RIP) - Instead of enforcing an element-wise restcriction on the off-diagonals of the matrix 𝐀𝑇𝐀, RIP (at a level 𝑠) requries a more general assumption that all 𝑠-sized principal block sub-matrices of 𝐀𝑇𝐀 are 𝛿𝑠 close to 𝐈𝑠 in the operator norm, i.e., ∥𝐀𝑇𝐒𝐀𝐒−𝐈𝑠∥2 ≤𝛿𝑠. Note that this also implies the below inequality (1 −𝛿𝑠)‖𝐯‖22 ≤‖𝐀𝐯‖22 ≤(1 +𝛿𝑠)‖𝐯‖22 ∀ 𝐯 ∈ℝ𝑑 s.t. ‖𝐯‖0 ≤𝑠. It can be easily shown that Mutual Incoherence ⟹ RIP via (𝛿𝑠≤𝑀(𝑠−1) ∀ 𝑠≥2). Refer Lemma A.1, Donoho, Elad, Temlyakov for a short proof.
- Restricted Null Space property - Implies that all the vectors in the null space of 𝐀 (except 𝟎) are far from being sparse. This property essentially characterizes when ℓ1 based sparse recovery algorithms work. Formally it requires {𝐯∈ℝ𝑑∣𝐀𝐯=𝟎}∩{𝐯∈ℝ𝑑∣‖𝐯𝐒𝖼‖1≤‖𝐯𝐒‖1}=𝟎. Restricted Null Space property an even weaker assumption than RIP.
- Restricted Strong Convexity (RSC) - This is a generalization of RIP as in the contraction that 𝐀 as an operator can perform on any 𝑠-sparse vector 𝐯 can be arbitrariliy small (but not 0). It essentiall means that there is a significant difference (in the ℓ2 norm sense) in the responses of 2 candidate sparse vectors which differ in their support by at most 𝑠. Formally, ‖𝐀𝐱−𝐀𝐳‖22 ≥𝜌−𝑠‖𝐱−𝐳‖22 ∀ 𝐱,𝐳 ∈ℝ𝑑 s.t. ‖𝐱−𝐳‖0 ≤𝑠 where 𝜌−𝑠 is the RSC constant at the level 𝑠. RSC is the weakest and the most popular asumption of all mentioned for sparse regression problems studied in the context of various algorithms.
Mutual Incoherence ⟹ RIP ⟹ Restricted Null Space Property ⟹ RSC.
The Linear form of Sparse Linear Regression (𝖲𝖫𝖱) is a representative problem and results typically extend easily to the general case. We consider the statistical setting of 𝖲𝖫𝖱 where the response is corrupted by adding an i.i.d. gaussian noise vector. We attempt to study this problem under the RSC assumption for a greedy algorithm Orthogonal Matching Pursuit algorithm.
𝐲=𝐀¯𝐱+𝜼=𝐀𝐒∗¯𝐱𝐒∗+𝜼where 𝜼 ∼N(𝟎,𝜎2𝐈𝑛) has i.i.d. normally distributed elements with variance 𝜎2, and supp(¯𝐱) =𝑠∗.
Questions of interest
- For any sparse regression algorithm, bounding the generalization error under a statistical model is a major machine learning goal. Here, the generalization error is defined as 𝐺(𝐱) =1𝑛‖𝐀𝐱−𝐲‖22 where the rows of 𝐀 are i.i.d. samples from some data distribution.
- Bounding the generalization error alone does not guarantee that the algorithm recovers the true support. This can be loosely answered by arguing if the algorithm can output a support set 𝐒 such that 𝐒 ⊇𝐒∗. Ideally one would like to have the smallest such set 𝐒 satisfying the superset condition.
It is to note that given support recovery, smaller the support set size, lower is generalization error. Recovering the true support is a fundamentally harder problem as strong support recovery results usually tend to provide strong generalization error bounds.
Below we describe the 2 algorithms we looked at during the project span.
Algorithms for Sparse Linear Regression
Broadly, existing sparse regression algorithms can be broadly categorized into 3 categories.
- ℓ1 minimization or LASSO based algorithms. E.g. - Dantzig selector etc.
- Non-convex penalty based. E.g. - Iterative Hard Thresholding, Penalty based methods like SCAD penalty, Log-sum penalty etc.
- Greedy methods. E.g. - Orthogonal Matching Pursuit (OMP) etc.
Iterative Hard Thresholding
Iterative Hard Thresholding as from the name suggests, takes a dense gradient step from the current 𝑠-sparse iterate at each iteration, and projects the dense iterate back to the 𝑠-sparse set by keeping only the top 𝑠 elements in terms of their absolute values. We fix a learning rate, and start at 𝐱0 =𝟎. At the 𝑡𝑡ℎ iteration
- 𝐱𝑡+1 =P𝑠(𝐱𝑡−𝜂∇𝐱𝑓(𝐱𝑡)).
where P𝑠 is the operator that projects its arguments to the 𝑠-sized ℓ0 ball. This can be easily done via sorting the elements of the argument vector based on their absolute values. The algorithm starts at 𝟎 and refines the solution at each step keeping only the 𝑠 dominant values in its iterates.
Orthogonal Matching Pursuit
As a greedy algorithm, OMP is one of the most simple and classical algorithm that works in an incremental fashion such that at each step, one feature is added to the support set based on a criterion, and so the size of the support set of equal to the number of steps OMP is run.
We start with the null set with the initial estimate of the solution being 𝟎. At each step, we compute the residual and look at the remaining features to see which feature best explains the residual and include the feature into the support set. The next iterate is the one which best optimizes the convex quadratic loss with the support of the variable restricted to the current support set. This can be easily computed using a least squares solver.
Compactly, with 𝐒0 =𝜙, 𝐱0 =𝟎, 𝐫0 =𝐲 −𝐀𝐱0 =𝐲. At the 𝑘𝑡ℎ iteration,
- 𝑗 ←argmax𝑖∉𝐒𝑘−1∣𝐀𝑇𝑖𝐫𝑘−1∣
- 𝐒𝑘 ←𝐒𝑘−1 ∪{𝑗}
- 𝐱𝑘 ←argminsupp(𝐱)⊆𝐒𝑘‖𝐀𝐱−𝐲‖22
- 𝐫𝑘 ←𝐲 −𝐀𝐱𝑘 =𝐲 −𝐀𝐒𝑘𝐱𝑘
Interestingly, note that ∣𝐀𝑇𝑖𝐫𝑘−1∣ ∝[∇𝑓(𝐱𝑘−1)]𝑖 for 𝑓(𝐱) =‖𝐀𝐱−𝐲‖22 and the algorithm can be easily modified for a general function 𝑓 for which step 3 is cheap.
Quantities of interest
To formalize the problem, let us define some key problem dependent quantities on which the problem depends on
- Restricted Smoothness (𝜌+𝑠) and Restricted Strong Convexity (𝜌−𝑠) - 𝜌−𝑠‖𝐱−𝐳‖22≤‖𝐀𝐱−𝐀𝐳‖22≤𝜌+𝑠‖𝐱−𝐳‖22∀ 𝐱,𝐳 s.t. ‖𝐱−𝐳‖0≤𝑠.
- Restricted Condition number (̃𝜅𝑠) - ̃𝜅𝑠=𝜌+1𝜌−𝑠
- We also define the quantity similar to usual condition number where both the Restricted Smoothness and the Restricted Strong Convexity are at the same level 𝑠 𝜅𝑠=𝜌+𝑠𝜌−𝑠≥̃𝜅𝑠
The Restricted Condition number is essentially a normalized way of referring to the inverse Restricted Strong Convexity, and therefore is a measure that determines the hardness of the problem.
Lower bounds for Fast Rate
Let us say for a moment that one can actually find the best minimizer to the 𝖲𝖫𝖱 problem. Let ˆ𝐱ℓ0 be the best ℓ0 estimate in the set of all 𝑠∗-sparse vectors. Then one can show that the expected generalization error for the worst problem is upper bounded by the fast rate, that is
sup‖¯𝐱‖0≤𝑠∗𝔼[∥𝐀(ˆ𝐱ℓ0−¯𝐱)∥22]≲1𝑛𝜎2𝑠∗log𝑑But the question than one might ask is how can one compute the estimate ˆ𝐱ℓ0? Because this problem is NP-hard, one trivial way therefore is to search over all (𝑑𝑠∗) 𝑠∗ sized subsets of [𝑑]. This is practically infeasible due to its complexity, therefore bounding the generalization error under the restriction that the estimate is polynomial time computable is a more practical question to ask.
Y. Zhang, M. Wainwright & M. Jordan’ 2014 come up with a lower bound proving that there exists a bad design matrix 𝐀bad, such that if ˆ𝐱poly is the output of any polynomial time algorithm, then the generalization error is lower bounded by a similar quantity but with an extra factor of ̃𝜅𝑠∗.
sup‖¯𝐱‖0≤𝑠∗𝔼[∥𝐀bad(ˆ𝐱poly−¯𝐱)∥22]≳1𝑛𝜎2̃𝜅𝑠∗𝑠∗log𝑑As a consequence to their work, any estimator ˆ𝐱 that achieves the fast rate must either not be polynomial time computable, or must not return a 𝑠∗-sparse vector.
The tightest upper bounds on the generalization error known before this work for algorithms like IHT, OMP and Lasso were at least ̃𝜅 times worse than this lower bound. A question then arises from this gap is whether the lower bound is itself loose or if there exists an algorithm for which we can have a better upper bound matching the known lower bound up to constants.
Attempts with IHT
To understand the gap better, we first started off by trying to tighten the upper bound proven by Jain et. al. for a candidate algorithm, Iterative Hard Thresholding. Their analysis requires IHT to be run at a level 𝑠 ≥𝛺(𝜅2𝑠𝑠∗) for linear convergence in the function space. Bringing it down to 𝑠 ≥𝛺(𝜅𝑠𝑠∗) would result in a much better generalization error bound than the ones they have. We tried incorporating several variants of acceleration into IHT to bring down the required expansion to at least 𝑠 ≥𝛺(𝜅𝑠𝑠∗) but the trivial analysis breaks down at certain points. However, there are strong empirical instances where Gradient Descent based IHT is inferior to Accelerated IHT.
The above plot describes how the error ∥𝐀ˆ𝐱𝑠−𝐲∥2 changes when we run IHT up to convergence at level 𝑠 (on the x-axis). The blue-dashed line represents the Euclidean norm of the noise. We see that Accelerated IHT uniformly achieves lower function value and dips earlier than the vanilla IHT. It was also observed that the rate of convergence of Accelerated IHT is much better than vanilla IHT and exhibits an oscillation behavior just like the error dynamics in the usual Nesterov’s acceleration.
Attempts with OMP
We restart exploring this gap by considering the classical algorithm OMP. Because OMP is a greedy algorithm, coming up with a lower bound instance for the support recovery is easy. For this we need to construct a matrix 𝐌 such that it has a controlled Restricted Condition number ̃𝜅𝑠 but still with high probability, at each step OMP ends up picking incorrect features and recovers the true support at the near end. Because the generalization error typically increases as the algorithm picks incorrect features, the generalization error incurred by OMP would be high.
Lower bound instance construction
We construct a parameterized matrix 𝐌(𝜖) ∈ℝ𝑛×𝑑(𝑑 ≤𝑛) by 0 ≤𝜖 ≤1 such that all the 𝑠∗ columns of the true support 𝐒∗ are orthogonal and the remaining columns are linear combinations of the mean of the true features and vectors orthogonal to their subspace. Precisely,
- 𝐌(𝜖)1:𝑠∗ are random 𝑠∗ orthgonal vectors s.t. ∥𝐌(𝜖)𝑖∥22 =𝑛 ∀ 𝑖 ∈[𝑠∗].
- 𝐌(𝜖)𝑖 =√1−𝜖[1√𝑠∗𝑠∗∑𝑗=1𝐌(𝜖)𝑗] +√𝜖𝐠𝑖 ∀𝑖 ∉[𝑠∗] where 𝐠𝑖’s are orthogonal to each other and 𝐌(𝜖)1:𝑠∗ with ‖𝐠𝑖‖22 =𝑛.
Below is a sketch to illustrate an example with 𝑛 =𝑑 =3,𝑠∗ =2 and 𝜖 =0.25.
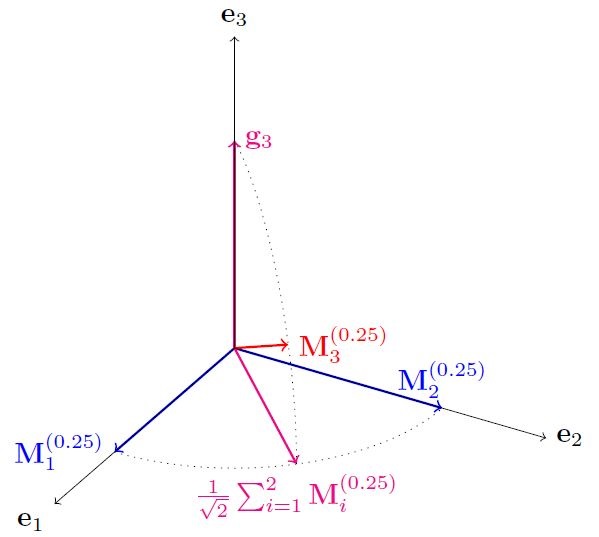
Note that by tuning 𝜖, we can either make the incorrect features very close to the subspace spanned by the correct features or keep then almost orthogonal. This is evident if we take the dot product of a correct feature 𝑖 ∈𝐒∗ with an incorrect feature 𝑘 ∉𝐒∗.
⟨𝐌(𝜖)𝑖,𝐌(𝜖)𝑘⟩=⟨𝐌(𝜖)𝑖,√1−𝜖[1√𝑠∗𝑠∗∑𝑗=1𝐌(𝜖)𝑗]+√𝜖𝐠𝑘⟩=⟨𝐌(𝜖)𝑖,√1−𝜖1√𝑠∗𝐌(𝜖)𝑖⟩=𝑛√1−𝜖𝑠∗ Therefore higher 𝜖 implies lower cross-set inner products, which in turn implies lower Restricted Condition number. We cannot set 𝜖 to be very high as we will not be able to fool OMP into picking up incorrect features. Therefore we can solve for the interval of 𝜖 so that OMP at each step picks up an incorrect feature.
We easily show that under the noiseless setting (𝜎 =0), if OMP is run on 𝐌(𝜖) for 𝜖 <1 −1𝑠∗, then OMP will continue including incorrect features until only the correct ones are left. Because we want Restricted Condition number to be as low as possible so that OMP fails, any value of 𝜖 =1 −𝛼𝑠∗ is good for constant 𝛼 >1.
Upper Bounding Generalization Error
The tightest known upper bounds for polynomial time algorithms like IHT, OMP and Lasso were at least ̃𝜅 times worse than the fast rate lower bound. Lemma A.5, T. Zhang’ 10 have the loose upper bound on the sub-optimality gap but after only 𝑠 =Θ(̃𝜅𝑠log𝜅𝑠𝑠∗) steps. This result gives a hint and a hope for a stronger generalization error because of the lower order of iterations. We exploit their line of analysis and tighten their sub-optimality gap by a factor of 𝜅𝑠
Result directly using T. Zhang’s bound - If ˆ𝐱𝑠 is the outout of OMP after 𝑠 =Θ(̃𝜅𝑠log𝜅𝑠𝑠∗) iterations, then with high probability
1𝑛∥𝐀(ˆ𝐱𝑠−¯𝐱)∥22≲1𝑛𝜎2𝑠∗̃𝜅2𝑠+𝑠∗log𝜅𝑠+𝑠∗log𝑑
Upon slight modifications and tightening T. Zhang’s analysis, we prove a better generalization bound that matches the fast rate up to logarithmic factors in 𝜅.
Result after modifying T. Zhang’s analysis - If ˆ𝐱𝑠 is the outout of OMP after 𝑠 =Θ(̃𝜅𝑠log𝜅𝑠𝑠∗) iterations, then with high probability
1𝑛∥𝐀(ˆ𝐱𝑠−¯𝐱)∥22≲1𝑛𝜎2𝑠∗̃𝜅𝑠+𝑠∗log𝜅𝑠+𝑠∗log𝑑
Gaussian Ensemble upper bounds
We can instantiate the above results for Gaussian ensembles, i.e. when the rows of 𝐀 are sampled from a multivariate Gaussian distribution N(𝟎,𝚺). If 𝜎max and 𝜎min are the maximum and minimum singular values of 𝚺, and 𝜅(𝚺) =𝜎max/𝜎min is its condition number, then we achieve the best known generalization error guarantee in terms of the dependence on 𝜅(𝚺).
Generalization error for Gaussian Ensemble - If 𝚺𝑖𝑖 ≤1 ∀ 𝑖 ∈[𝑑], 𝑛 =𝛺(𝑠log𝑑𝜎min) and if ˆ𝐱𝑠 is the output of OMP after 𝑠 =Θ(𝜅(𝚺)log𝜅(𝚺)𝑠∗) iterations where 𝐒 =supp(ˆ𝐱𝑠), then with high probability,
1𝑛∥𝐀(ˆ𝐱𝑠−¯𝐱)∥22≤1𝑛𝜎2𝜅(𝚺)log𝜅(𝚺)𝑠∗log𝑑
This result is a corollary of the general generalization upper bound result using some concentration results.
Support Recovery upper bound
Loh’ 14 have strong support recovery results on non-convex regularization based algorithms that use SCAD/MCP like penalty, but they require the mutual incoherence of the matrix 𝐀 to be bounded by 1 which is independent of any problem parameter and is too much to ask for. For greedy algorithms like HTP and PHT however, we have doubts about the correctness of the analysis in the latter result.
We prove and exploit a crucial property for OMP that if at any iteration there is a true feature that is not recovered and if the smallest absolute value of the true solution ¯𝐱 that is |¯𝑥min| is greater than an appropriate noise level, then there is a significant decrease in the objective function. Precisely, we have that
Large decrease in objective - If ˆ𝐱𝑠 is the output of OMP after 𝑠 =Ω(̃𝜅𝑠log𝜅𝑠𝑠∗) iterations s.t. 𝐒∗ ∖𝐒 ≠𝜙 and |¯𝑥min| ≳𝜎𝛾√𝜌+1𝜌−𝑠+𝑠∗, then with high probability
∥𝐀ˆ𝐱𝑠−𝐲∥22−∥𝐀ˆ𝐱𝑠+1−𝐲∥22≳𝜎2log𝑑where ∥𝐀𝑇𝐒∗∖𝐒𝐀𝐒(𝐀𝑇𝐒𝐀𝐒)−1∥∞ ≤𝛾 and 𝐒 =supp(ˆ𝐱𝑠).
We note that the 𝛾 in this result is similar to the mutual incoherence condition and is not required to be bounded by a universal constant and can be very large. This crucially helps us to show that the condition that there are some true features are left out, cannot be true for very long because if it is true then at each step we have a good decrease in the function value and because the function value is non negative and nicely lower bounded, all the true features must be included in the support and we must have supp(ˆ𝐱𝑠+𝑘 ⊇𝐒∗) for a small value of 𝑘. In fact, it can be shown that 𝑘 =Θ(𝑠) suffices which allows us to prove the following theorem
Support recovery upper bound - If ˆ𝐱𝑠 is the output of OMP after 𝑠 =Ω(̃𝜅𝑠log𝜅𝑠𝑠∗) iterations, ∥𝐀𝑇𝐒∗∖𝐒𝐀𝐒(𝐀𝑇𝐒𝐀𝐒)−1∥∞ ≤𝛾, 𝐒 =supp(ˆ𝐱𝑠), and |¯𝑥min| ≳𝜎𝛾√𝜌+1𝜌−𝑠+𝑠∗ then with high probability 𝐒∗ ⊆supp(ˆ𝐱𝑠).
It is to note that the assumption on |¯𝑥min| satistically relaxes out with increasing number of data points 𝑛. This is because both 𝜌+ and 𝜌− have a factor of 𝑛 in them amd the bound depends on √𝜌+1𝜌−𝑠+𝑠∗ ∝1√𝑛.
𝜌−𝑠‖𝐯‖22≤‖𝐀𝐯‖22=𝐯𝑇𝐀𝑇𝐀𝐯=𝑛𝐯𝑇1𝑛𝐀𝑇𝐀𝐯=𝑛𝐯𝑇ˆ𝚺𝐯𝜌+𝑠‖𝐯‖22≥‖𝐀𝐯‖22=𝐯𝑇𝐀𝑇𝐀𝐯=𝑛𝐯𝑇1𝑛𝐀𝑇𝐀𝐯=𝑛𝐯𝑇ˆ𝚺𝐯 for ‖𝐯‖0 ≤𝑠. ˆ𝚺 is the empirical second order moment matrix of 𝐀 and converges to the true second order moment as 𝑛 increases.
Using this support recovery result, we can also bound the element-wise error i.e., ∥ˆ𝐱𝑠−¯𝐱∥∞.
Infinity norm error bound - As a consequence of support recovery from the above theorem under the same assumptions, we have
∥ˆ𝐱−¯𝐱∥∞≲𝜎√log𝑠𝜌−𝑠
Note that the bound on the infinity norm requires support recovery and is √̃𝜅 lower the known bounds in other works. We currently are trying to bound the infinity norm even if support recovery has not taken place. This essentially requires to prove that the infinity norm of the true solution on the unrecovered support set is bounded. Such a result is an interesting approximation because in practice we might not know if full support recovery has taken place but still an element-wise bound would hold and one can think of pruning down the elements of the estimate to get better support sets or even come up with a stronger algorithm in practice.
Matching lower bounds for generalization error and support recovery
It turns out that the simple matrix 𝐌(𝜖) and ¯𝐱 construction, as discussed earlier leads to lower bounds for both generalization and support recovery for OMP or proper choices of 𝜖. To show this, we first analyze how the Restricted Condition number 𝜅𝑠 and 𝛾 depends on 𝑠 and 𝜖 and then we can choose proper 𝜖 ∈(0,1) so that the assumptions of the upper bound theorems are satisfied and still OMP fails to have good generalization error as well as support recovery in good number of steps.
The matrix class 𝐌(𝜖) satisfies
- ̃𝜅𝑠(𝐌(𝜖)) ≤4(1 +2(1 −𝜖)𝑠) =𝑂(𝑠), and
- 𝛾(𝐌(𝜖)) ≤1√𝑠∗(1−𝜖) for 𝐒 ∩𝐒∗ =𝜙
Proving a lower bound for the noiseless version of 𝖲𝖫𝖱 is relatively easier and the below theorem states the result
Lower bound for noiseless 𝖲𝖫𝖱 - For all 𝑠∗ ≤𝑑 ≤𝑛, there exists a design matrix 𝐌(𝜖) and a 𝑠∗-sparse vector ¯𝐱 such that when OMP is executed on the corresponding 𝖲𝖫𝖱 problem, then for 𝑠 ≤𝑑 −𝑠∗ we have
- ̃𝜅𝑠(𝐌(𝜖)) ≤𝑂(𝑠𝑠∗) (or 𝑠 ≥𝛺(̃𝜅𝑠𝑠∗)) and 𝛾 ≤𝑂(1), and
- 𝐒∗ ∩supp(ˆ𝐱𝑠) =𝜙
The result indeed tells that for OMP one needs to at least go till a level of 𝑠 ≥𝛺(̃𝜅𝑠𝑠∗) to uniformly guarantee support recovery. The lower bound result in Y. Zhang, M. Wainwright & M. Jordan’ 2014 does not hold for OMP because the sparsity of the estimate of OMP is equal to the number of iterations to which it has been run, and their lower bound holds for algorithms which exactly outputs a 𝑠∗-sparse estimate. Our lower bound construction is specific for OMP. We also look at the bad matrix constructed in Y. Zhang’s work and find that for our uniform ¯𝐱 construction, OMP recovers the true support in 𝑂(𝑠∗) steps with 𝑛 =Θ(𝑠∗log𝑑) samples despite the fact that the restricted condition number of their bad matrix is high. So in general, large condition number alone does not imply difficulty in recovery for OMP.
For noiseless 𝖲𝖫𝖱, the question of generalization error does not arise because 𝜎 =0. For the noisy case, we again have the same matrix construction 𝐌(𝜖) with an appropriate 𝜖 so that with high probability we do not recover the full support and also the generalization error is large. The proof that there is no support recovered by OMP until the near end (𝑠 ≤𝑑1−𝛼 for 𝛼 =𝑜(1)), involves an intricate argument of order statistics of correlated Gaussian random variables, which is non-trivial.
Lower bound for noisy 𝖲𝖫𝖱 - For 𝑠∗ ≥8 and 𝑑 ≥𝛺(1), there exists a design matrix 𝐌(𝜖) and a 𝑠∗-sparse vector ¯𝐱 s.t. if OMP is run on the corresponding 𝖲𝖫𝖱 problem, then for 𝑠 ≤𝑑1−𝛼 for some 𝛼 =𝑜(1), with high probability,
- ̃𝜅𝑠(𝐌(𝜖)) ≤𝑂(𝑠𝑠∗) (or 𝑠 ≥𝛺(̃𝜅𝑠𝑠∗)) and 𝛾 ≤𝑂(1),
- 1𝑛∥𝐀(ˆ𝐱𝑠−¯𝐱)∥22 ≳1𝑛𝜎2̃𝜅𝑠+𝑠∗𝑠∗log𝑑, and
- 𝐒∗ ∩supp(ˆ𝐱𝑠) =𝜙.
We think that the condition 𝑠 ≤𝑑1−𝛼 is important because of the randomness in the support selection step of the algorithm introduced because of the noise vector 𝜂 and one might not expect complete disjointness until the very end, i.e., 𝑠 ≤𝑑 −𝑠∗, supp(ˆ𝐱𝑠) ∩𝐒∗ =𝜙. In specific, one can think of 𝛼 ≃loglog𝑑log𝑑 which would require 𝑑 ≥55 as a mild assumption in our analysis.
Simulations
We also verify our results by performing some simulations. We generate our lower bound matrix 𝐌(𝜖) ∈ℝ1000×100 and a fixed 𝑠∗ =10-sparse vector ¯𝐱 with 𝐒∗ =supp(¯𝐱). The response 𝐲 is generated as 𝐲 =𝐌(𝜖)¯𝐱 +𝜼 where 𝜂 ∼N(𝟎,𝜎2𝐈𝑛). We denote ˆ𝑠(𝜖) as the support set size when full support recovery takes place, i.e., ˆ𝑠(𝜖) =supp(ˆ𝐱) is the smallest integer such that supp(ˆ𝐱ˆ𝑠(𝜖)) ⊇𝐒∗ holds. Because of the explicit construction of 𝐌(𝜖), we can compute the exact ̃𝜅(𝐌(𝜖)) which will be a function of 𝜖. In general, the Restricted Condition number of 𝐌(𝜖) increases with decreasing 𝜖 as noted earlier. We vary 𝜖, which varies ̃𝜅(𝐌(𝜖)) and plot ˆ𝑠(𝜖) for 𝜎2 =0,0.5 and 1.
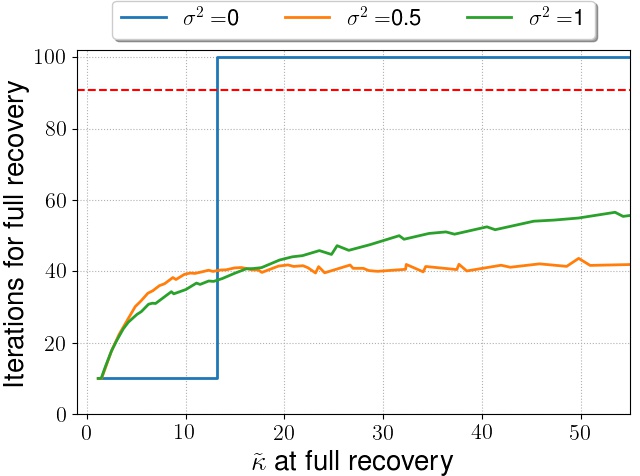
We clearly see the criticality of ̃𝜅 for OMP’s support recovery property on our lower bound instance 𝐌(𝜖) for an appropriate 𝜖, when for the noiseless case (𝜎2 =0), we observe that there is a sharp threshold of ̃𝜅 before which OMP takes exactly 𝑠∗ steps to recover the support and after which OMP recovers the full support at the very end (𝑑𝑡ℎ iterate).
Because 𝐌(𝜖) is explicitly constructed so that OMP on the noiseless version of 𝖲𝖫𝖱 version drastically fails, implies that addition of noise in the corresponding 𝖲𝖫𝖱 problem will only help OMP because of the noise introduced in the selection step of OMP and one would expect that when noise is very high, the selection step of OMP tends to become a random selector. This behaviour is clearly observed when we plot ˆ𝑠(𝜖) =supp(ˆ𝐱) with respect to 𝜎2 after sufficient averaging.
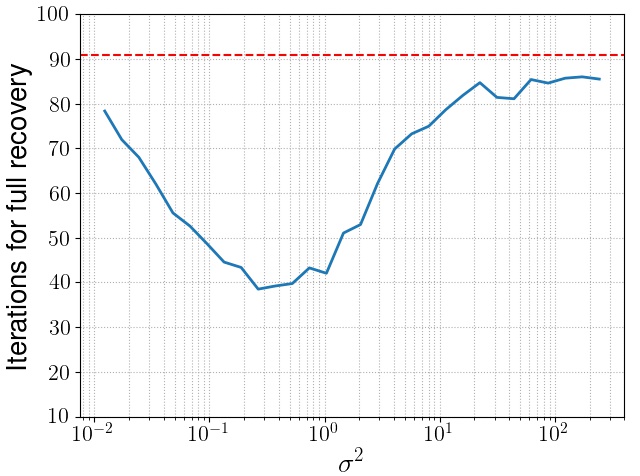
We see that when the noise is low, OMP struggles to capture the complete support. As we slowly increase the noise, the randomness introduced helps OMP recover the correct features; when the noise is very high, OMP’s selection step essentially tends to become a uniform random selector. This is represented by the red dashed horizontal line with equation lim𝜎2→∞𝔼𝜼∼N(𝟎,𝜎2𝐈𝑛)[ˆ𝑠(𝜖)] =𝑠∗𝑠∗+1𝑑. This behavior exactly matches what is expected from our upper and lower bound results on OMP’s support recovery.
The work was presented at Microsoft Research India Labs after the work on OMP got selected for a spotlight presentation at NeurIPS 2018. Find the presentation here.
Publication resources:
- NeurIPS poster.
- Proceedings and paper.
- Spotlight slides.
- Spotlight video presentation (from 1:36:20).